 Forum
01
Notice a sustained group condition.
Configure meaningful device groups, failure thresholds and persistence windows.

Notice a shared failure. Coordinate the response. Follow recovery.
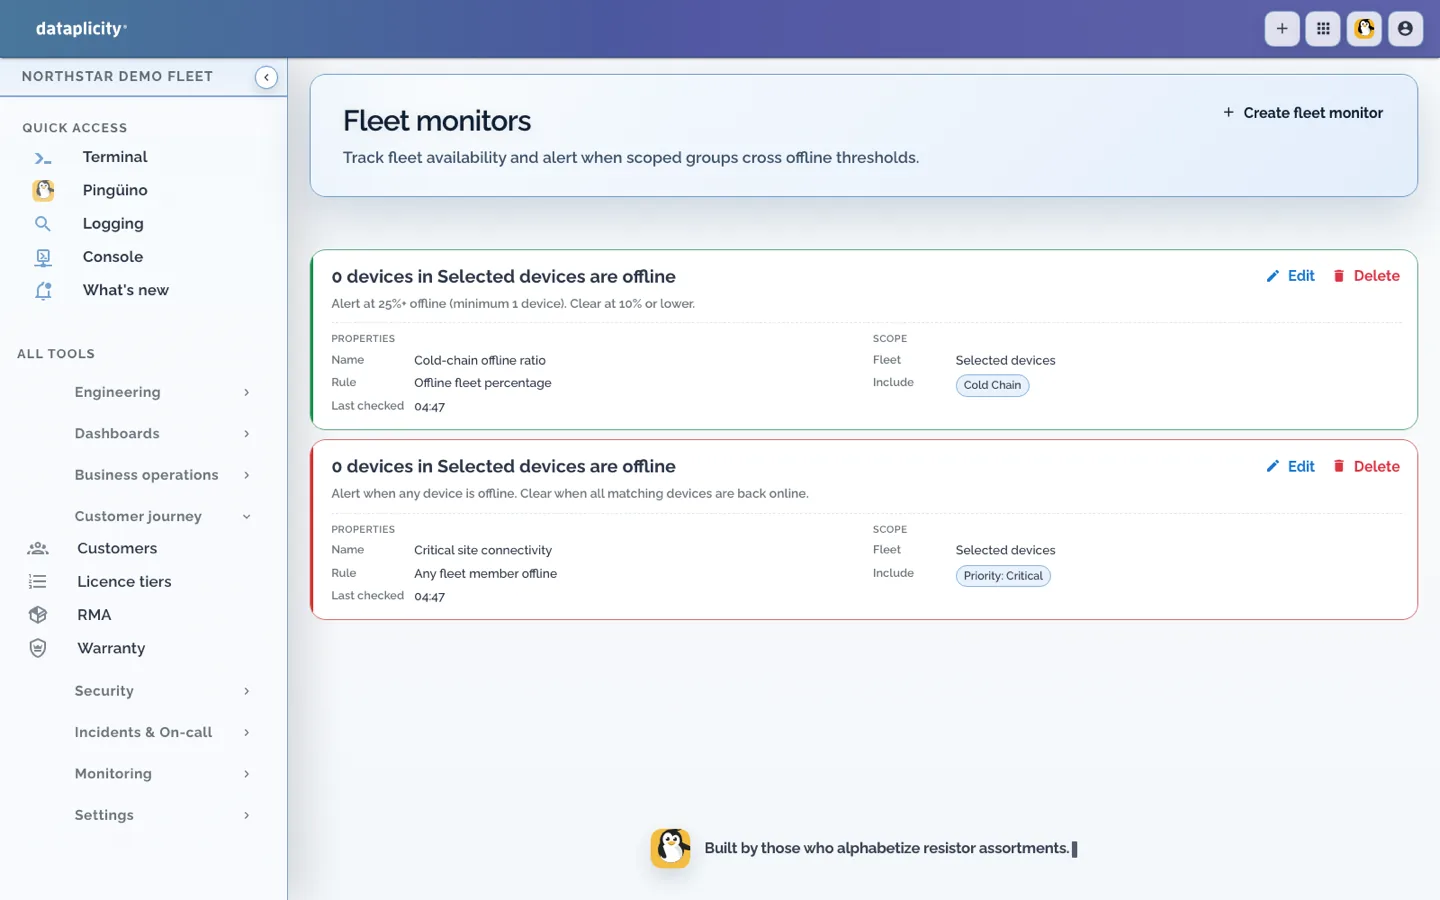
Configured fleet monitors · Northstar demo fleet
Configure meaningful device groups, failure thresholds and persistence windows.
Compare healthy equipment, inspect collected history and coordinate the incident.
Check fresh device and service evidence. Keep unresolved units visible.
Fleet monitoring and incidents require Business+. Compare carrier and service evidence before assigning a cause.
Setup and technical guides ↓Choose the setup question or guide you need.
Illustrative operating sequence. People choose the scope and intervention; configured collection, rules and device behaviour supply the evidence.
For example, group gateways that use T-Mobile. Verify the active carrier on each device before recording it in tags or groups. T-Mobile is an example, with no implied partnership.
Configure the affected proportion, persistence window and recovery criteria for a fleet monitor. Account for reporting coverage and missing observations; a quiet device and a measured service failure are different evidence.
Responders compare last-seen times, connection-quality history and healthy cohorts. The configured rule raises an incident and notification or on-call escalation. Review collected logs and security evidence; approve customer communication rather than broadcasting raw engineering information.
Check fresh check-ins and application/service evidence against the configured recovery condition. Keep remaining exceptions visible and record the outcome before closing the incident. Live access requires the affected agent to reconnect.
Group identity, monitor observations, incident notes and affected customer/site context support the handover between responders. Choose the relevant cohort explicitly. Correlation identifies a shared dependency to investigate; it does not prove T-Mobile caused the failure.
Previously collected history can support an offline investigation; missing observations must stay visible. Carrier causation and customer service restoration require further evidence.
Configuration, product engineering and subscription eligibility are different requirements.
Connect the fleet, maintain accurate membership, enable signals and configure thresholds, persistence, notification recipients and escalation. Test a synthetic failure and recovery with a limited demo group before relying on the policy.
Keep your equipment, chosen Linux, application and retained business tools. Provider contacts and external service-desk integration remain your responsibility where needed.
The fleet-monitoring and incident suite follows Business+ entitlement and current release access. Enterprise adds fleet SLO capabilities. Plan eligibility does not create your groups, alert policy or on-call rota.
Read the guide → →Use the exact implementation guides to check the supported contract and limits.
Configuration and implementation requirements.
Read the guide → →Configuration and implementation requirements.
Read the guide → →Configuration and implementation requirements.
Read the guide → →Ask for help where evidence or an integration decision is unclear. Use the context and permissions available to that conversation.
Equidna helps connect supplied hardware evidence to the software path; Nutria helps plan the customer job; Pingüino helps investigate authorised operational evidence. Shared-room help remains read-only. 24/7 AI assistance has plan and usage conditions.
Read the guide → →Use the reference to build your own test. Validate the hardware, integration and operating process on your product.
Review the procedure and qualify the parts your product requires.
Read the guide → →Start with the product you have, then choose independent optional paths.
Read the guide → →Connect the fleet, maintain accurate membership, enable signals and configure thresholds, persistence, notification recipients and escalation. Test a synthetic failure and recovery with a limited demo group before relying on the policy.