 Forum
Metric thresholds
Trigger alerts on CPU, memory, or custom metrics.

Set conditions for device health and availability, then route notifications to the people responsible. Check the affected devices and evidence before deciding what to do.
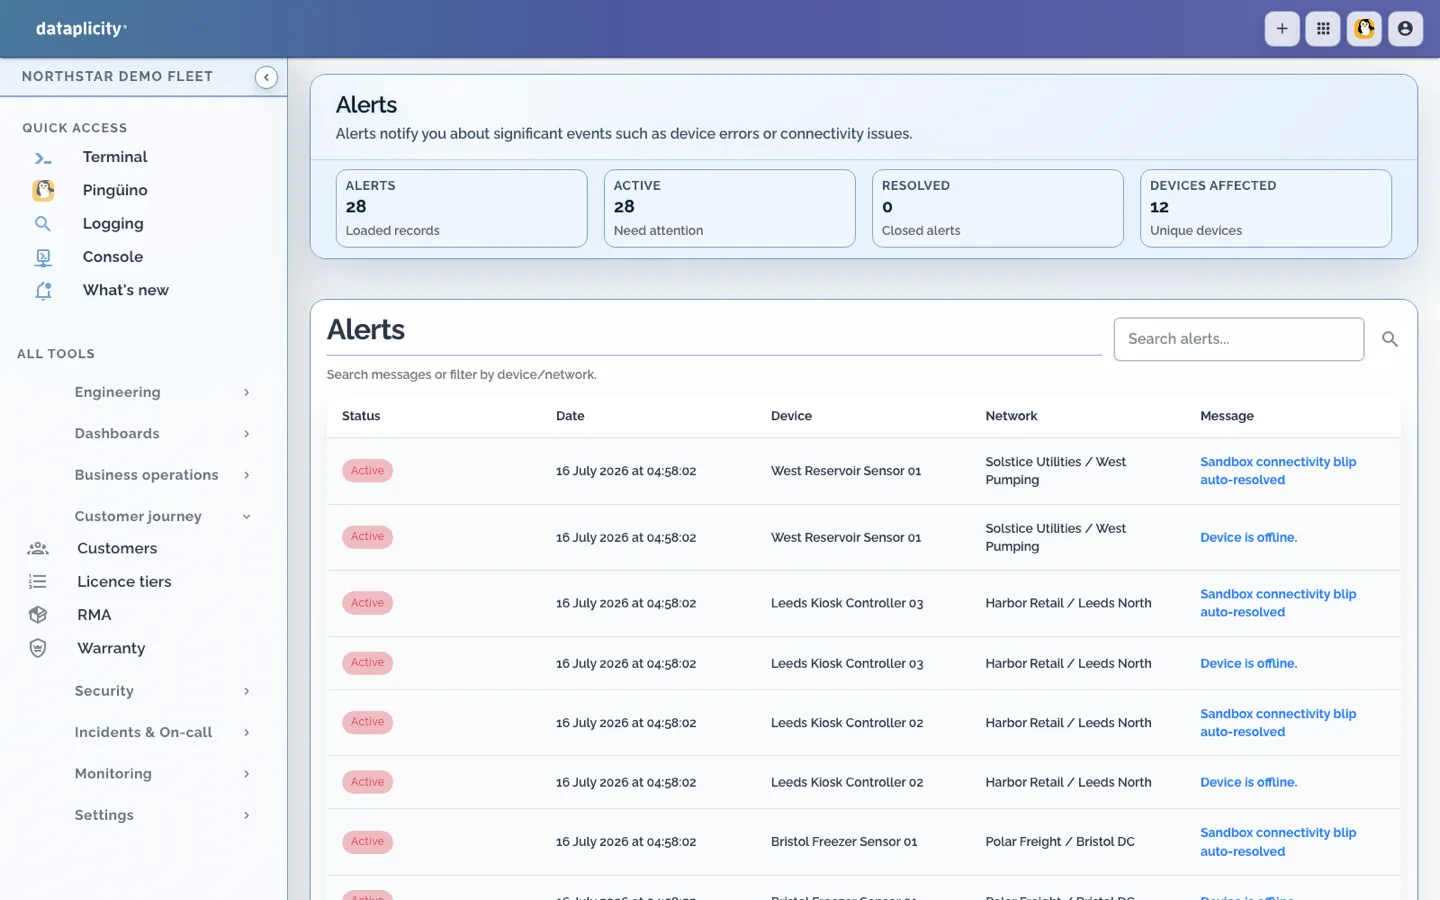
Define alert policies once and reuse them across cohorts.
Trigger alerts on CPU, memory, or custom metrics.
Alert when devices stop checking in.
Alert on fleet-wide ratios or availability.
Route alerts into incident workflows.
Route alerts to the correct rota.
Attach notes and resolution steps.
Track alert history against the device.
An alert is the start of the operating workflow. Keep the affected devices, response and evidence together.
Watch device and fleet conditions, compare ISP and site cohorts, and check which services are affected.
Explore this pathUse the Business+ incident and on-call suite for acknowledgement, escalation and investigation notes.
Explore this pathPublish appropriate customer updates, verify recovery across the affected group, and retain availability evidence. Fleet SLOs require Enterprise.
Explore this pathCreate alert rules and start getting notified.